Phase 01
Audit
We connect to Search Console, crawl the site, review rendering and Core Web Vitals field data, and read server logs where they are available.
Technical SEO makes sure search engines and AI crawlers can reach, render and understand your website. We are software engineers, so we don't stop at an audit: we find what stops your pages being crawled, indexed and shown, then fix it in your code, and we protect your rankings when you redesign or move platforms.
At a Glance
WHAT TECHNICAL SEO IS
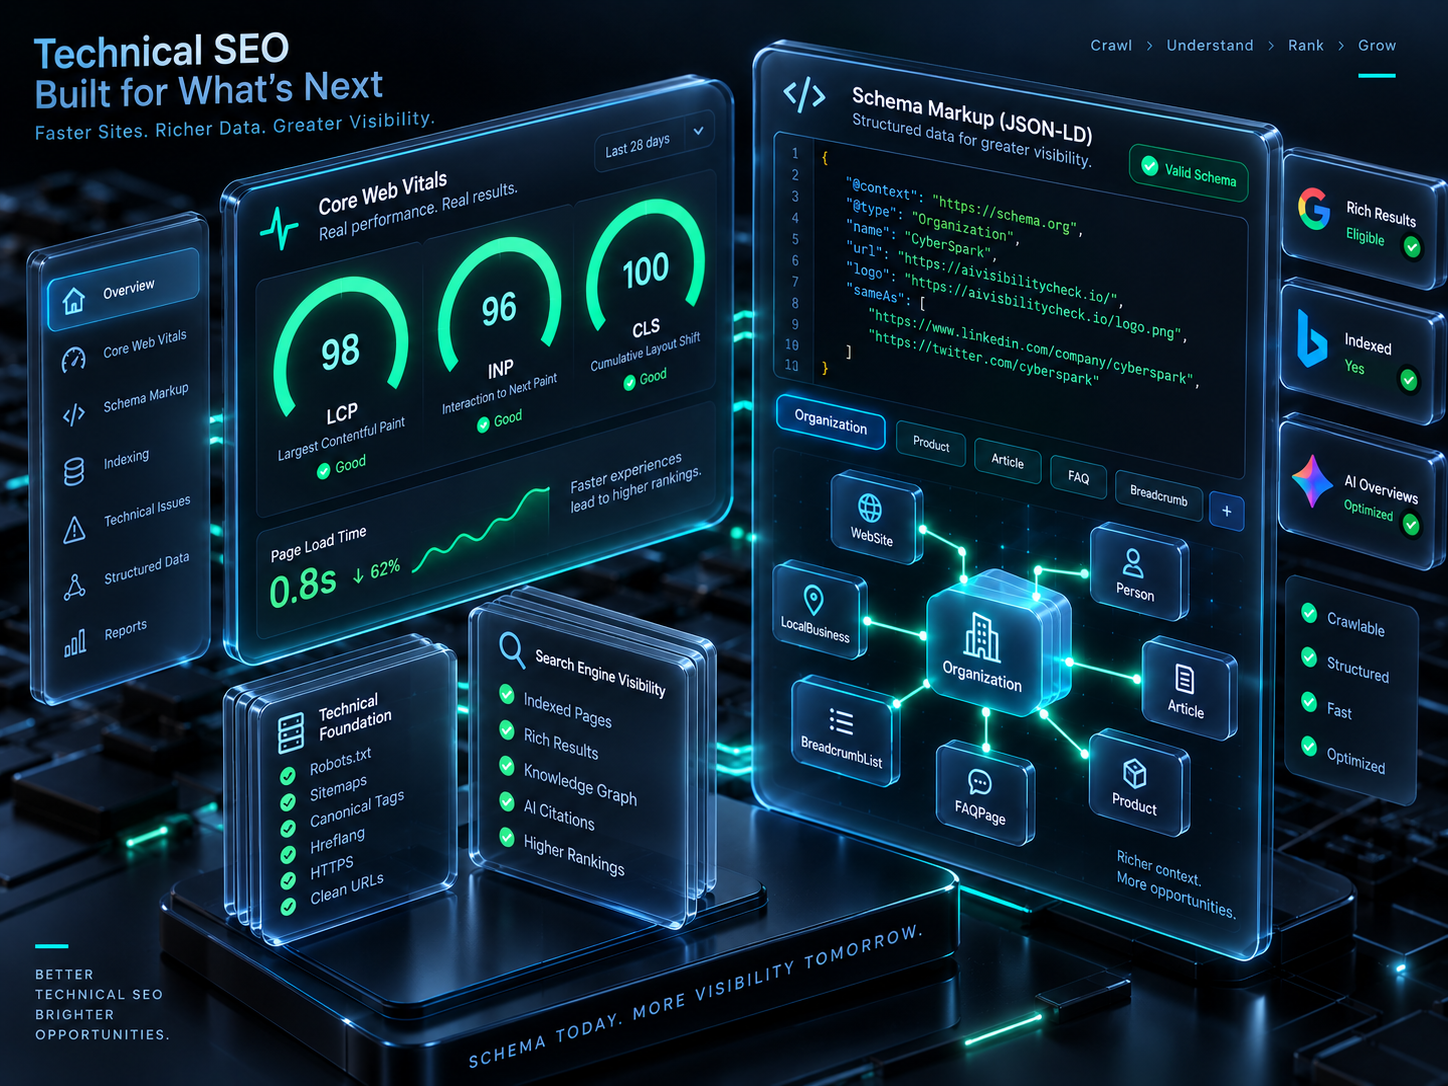
Good content can't rank if Google can't crawl it, can't render it, or doesn't know which version of a page to show. Technical SEO is the work on the website itself (its structure, code, speed and signals) that removes those obstacles.
You probably need a technical SEO audit if:
Technical SEO is not a one-off checklist. It matters most when something changes: a new site, a new platform, a new section, or a new country.
WHAT AN AUDIT COVERS
We start from your own data (Google Search Console, Bing Webmaster Tools and, where available, server logs), then crawl the site the way a search engine does.
| Area | What we check | Why it matters |
|---|---|---|
| Crawling | robots.txt, internal links, orphan pages, crawl traps, server errors, redirects and redirect chains | Search engines can only rank pages they can reach |
| Indexing | Canonical tags, noindex, duplicate and thin URLs, parameters, XML sitemaps, Search Console coverage | The right version of each page gets indexed, and only once |
| Rendering | Whether content and links exist in the HTML or only after JavaScript runs; server-side rendering or pre-rendering options | Crawlers that don't run JavaScript, and many AI crawlers, may see an empty page |
| Speed | Core Web Vitals (LCP, INP, CLS) from real-user field data, images, fonts, scripts, caching | A slow page loses visitors, and page experience is one of Google's signals |
| Structured data | Organization, Service, Product, Article, FAQ and breadcrumb markup, checked against Google's documentation | Helps search engines understand the page and qualify for rich results |
| Site architecture | URL structure, navigation depth, internal linking, pagination | Important pages should be easy to find for people and crawlers |
| International | hreflang tags, language and country versions, sitemaps per market | The right country version shows in the right search |
| Security and hygiene | HTTPS everywhere, mixed content, security headers, soft 404s | Broken signals erode trust and waste crawl effort |
Every finding comes with the evidence (the URL, what we saw, and why it matters), a priority based on the traffic at stake, and the fix. Where we can, the fix is a pull request, not a paragraph in a PDF.
SITE MIGRATIONS
A redesign, a new CMS or a domain change is the riskiest moment for your search traffic. Most losses come from a few avoidable mistakes: old URLs that stop working, redirects to the home page instead of the matching page, content dropped in the move, or noindex left on from staging.
How we protect a migration:
We did exactly this when we moved our own websites to a new platform: every existing address kept working, and each one was tested automatically before and after the switch.
HOW WE WORK
Evidence first, fixes in order of impact, and checks that stop problems coming back.
We connect to Search Console, crawl the site, review rendering and Core Web Vitals field data, and read server logs where they are available.
We turn the findings into a backlog your team can work from, in your tracker, with the fix for each issue and how to verify it.
Our engineers make the changes in your repository through pull requests your team reviews, or pair with your developers if you prefer to make them yourselves.
We watch indexing, Core Web Vitals and crawl errors after release, and add automated checks so a future deploy doesn't quietly undo the work.
JAVASCRIPT AND AI CRAWLERS
Google can render JavaScript, but rendering can come later than crawling, and a page that depends entirely on scripts is fragile. Many other crawlers, including most AI crawlers, read only the HTML they are sent. If your key content, links or structured data only appear after JavaScript runs, they may be invisible to them.
What we typically recommend:
<a href>) for navigation, not click handlers.If AI answers matter to you, our AI search visibility service builds on these foundations.
FREE TOOLS
We build our own diagnostics, and 11 of them are free to use on AI Visibility Check:
| Tool | What it checks |
|---|---|
| Schema checker | JSON-LD structured data on a page |
| Robots.txt checker | Which search and AI crawlers your robots.txt allows |
| Sitemap validator | XML sitemap structure and URLs |
| Hreflang checker | Language and country tags and their return links |
| Redirect checker | Redirect hops and chains for a URL |
| Security headers checker | HTTPS and browser security headers |
| On-page SEO checker | Titles, descriptions, headings and other on-page basics |
| SERP preview | How a title and description may look in results |
| Favicon checker | Favicon setup across browsers and search |
| llms.txt generator | A draft llms.txt file for your site |
| RAG extractability scorer | How easily an AI system can extract answers from a page |
They are a good first look. An audit adds your Search Console data, a full crawl and the judgement to decide what to fix first.
FREQUENTLY ASKED QUESTIONS
Straight answers about technical SEO audits, fixes and migrations.
EXPLORE FURTHER
Tell us what you're seeing (lost traffic, pages not indexed, a migration coming up) and an engineer will reply with practical next steps.